Sorry, there were no results found for “”
Sorry, there were no results found for “”
Sorry, there were no results found for “”
“Houston, we have a problem.”
All of us have used it at least once. It’s become shorthand for that sinking moment when something important breaks and you need a fix, fast.
At work, that usually means a problem that hits several teams. Like that one bug which survived several rounds of fixes, broke three customer databases, and is driving up support ticket volumes. It started in engineering, but now support, product, and customer success all own a piece of it.
What you need right then is a tiger team: a small, temporary group of specialists pulled together to solve one clearly defined, high-stakes problem. The idea began in the 1960s in aerospace and has since spread to engineering, government, security, and everyday operations.
Somewhere along the way, though, the label got stretched to cover almost any urgent meeting with a few senior people. We’ll break down what a tiger team actually is, where the term came from, and how it differs from the task forces and war rooms it often gets confused with.
Tiger teams pull a few specialists off their regular work to fix one specific, high-stakes problem, then hand the work back once it’s fixed. The term comes from 1960s aerospace and became famous after Apollo 13.
A tiger team is a short-term group with a single job: resolve one problem that the current structure can’t fix at the speed it needs.
The structure matters more than the label. A tiger team needs a defined outcome, the expertise to investigate it, and enough authority to act without becoming another standing committee.
Tiger teams typically share a few characteristics:
You can see this structure in the U.S. Department of Labor’s unemployment insurance Tiger Teams. Starting in 2021, the department brought together specialists in fraud prevention, customer experience, unemployment insurance, data, and systems engineering to assess problems in individual state programs and recommend near-term improvements. In their first 24 months, these teams worked with 36 states.
But not every tiger team will look identical. Some members may stay partly involved in their regular work, while others may step away from it completely.
The term dates back to American aerospace in the 1960s, long before it became common business-problem language.
One early documented use appears in the 1964 SAE paper Program Management in Design and Development by J. R. Dempsey, W. A. Davis, A. S. Crossfield, and Walter C. Williams. It described a tiger team as a group of “undomesticated and uninhibited technical specialists” chosen for their experience, energy, and imagination. Their job was to relentlessly search for possible sources of failure in spacecraft systems and simulations.
And these weren’t simply senior experts brought together in a room. They were expected to question assumptions, find weaknesses others had missed, and work outside some of the usual constraints around a program.
Six years later, Apollo 13 gave the term one of its most famous associations. On April 13, 1970, an oxygen tank exploded while the spacecraft was roughly 200,000 miles from Earth. Jack Swigert radioed Mission Control, “Houston, we’ve had a problem here,” a line that later entered popular culture as “Houston, we have a problem.”
NASA flight director Gene Kranz then led what NASA records describe as the Apollo 13 “Tiger Team,” working alongside the wider Mission Operations Team to solve the problems standing between the astronauts and a safe return. The Apollo 13 Mission Operations Team later received the Presidential Medal of Freedom for its role in the rescue.
Apollo 13 helped cement the tiger team as a model for concentrated problem-solving under pressure, but it didn’t coin the term.
Tiger teams are often confused with other group structures, such as task forces, war rooms, red teams, and skunkworks. They can all involve small groups working outside the usual team structure, but they’re assembled for different reasons.
| Structure | Main job | What separates it | Usually ends when |
|---|---|---|---|
| Tiger team | Solve one bounded, high-stakes problem | Specialists are chosen around the problem and given room to move quickly across normal team boundaries | The defined outcome is reached and ownership is handed back |
| Task force | Address a broader issue or initiative | Often coordinates work across several functions and may operate through the organization’s usual decision-making structure | Its recommendations are delivered or the wider initiative is complete |
| War room | Coordinate the response to an active incident | Centers on rapid communication, decisions, and status updates while the incident is unfolding | The immediate situation is stabilized |
| Red team | Expose weaknesses by thinking or acting like an adversary | Challenges a system, plan, or defense instead of owning the work required to fix every weakness it finds | The exercise is complete and findings have been documented |
| Skunkworks | Develop an experimental idea, technology, or product | Operates with unusual independence to explore and build something new, often over a longer period | The concept is abandoned, proven, or moved into a more permanent organization |
The easiest mix-up is between a tiger team and a task force because both can bring people together from several functions. The difference comes down to the mandate. A task force might investigate a broad issue, coordinate an initiative, or recommend changes. A tiger team is typically given a narrower problem and more freedom to work through it quickly.
A war room starts from a different place. It’s built around an incident that’s already unfolding and gives the people responding to it a shared place and cadence for decisions. A tiger team can emerge from a war room if the immediate incident reveals a deeper problem that requires concentrated work once the situation is stable.
Red teams are more deliberately adversarial. In cybersecurity, for example, NIST defines a red team as a group organized to emulate an adversary’s attack or exploitation capabilities. The goal is to find weaknesses by challenging the system. A tiger team may use that kind of thinking, but its broader responsibility is to solve the problem it was assembled around.
A skunkworks goes in another direction. The model, made famous by Lockheed Martin’s Skunk Works, gives a small group unusual autonomy to develop something new. Tiger teams are usually formed around a problem with an exit condition. Skunkworks teams can stay together much longer while an idea is explored, designed, and tested.
These distinctions matter because giving a group a more urgent-sounding name doesn’t change how it works. Before forming a tiger team, the better question is whether the problem calls for that particular structure in the first place.
A tiger team makes sense when a problem is cross-functional, requires specialist input, or has stalled in the normal process. But pulling specialists into a temporary team also pulls them away from work they already own.
A good case usually passes four tests:
The same model can also be used preventively, before a high-risk change reaches production or launch.
Skip forming a tiger team when the goal is still vague, the real problem is a staffing shortage, or the work already has a clear owner and can move through the normal process. If the same issue keeps calling for temporary rescue teams, that points to a need for permanent ownership or a structural fix.
A tiger team doesn’t need a large roster, but everyone should know what they’re responsible for. In most cases, you’ll need a few core roles:
One person can cover multiple roles in a small team. The key is that authority, day-to-day ownership, specialist expertise, and documentation each have a clear home.
Once the team is in place, the work needs enough structure to keep the investigation from turning into a stream of meetings, theories, and disconnected fixes. The following steps take the team from its first working session through validation and handoff.
Every tiger team needs an exit condition: the specific result that signals to everyone that the problem is resolved and the team can disband. Agree on it first, then turn it into something people can use to guide their daily decisions.
A short working brief usually does the job. It should answer:
Pay extra attention to the last question. Picture an operations team working through a growing processing backlog. Getting the queue under 500 cases might feel like a win for an afternoon. Keeping it there for a full week, while daily processing continues to outpace incoming work, is far stronger evidence that the fix will last.
Pro Tip: Pair the primary success metric with one guardrail metric. If you’re reducing checkout failures, for example, track refunds or support tickets alongside them so one improvement doesn’t hide a new problem.
2. Lock down roles, decision rights, and boundaries
Start by naming the lead, the sponsor, the specialists, and whoever will keep the working record up to date. Then settle the question of decision rights early. The team can make some calls on its own, some need the sponsor’s approval, and some still belong to the teams that normally own them.
The team also needs a clear boundary around its work. Before the investigation picks up speed, write down:
- The systems, teams, or processes the group is allowed to change
- The areas it can investigate but can’t alter without approval
- The risks that need immediate escalation
- The adjacent problems it should log and leave alone for now
That last item prevents a lot of drift. A payments investigation, for example, might turn up issues with pricing, account setup, or customer onboarding. Some of those may be worth fixing later, but folding them all into the current assignment is how a two-week effort turns into a two-month one.
Capacity needs the same attention. Reassign urgent commitments, move deadlines where you can, and tell the affected owners what’s changed. Otherwise, team members end up running the tiger team on top of everything they were already carrying.
By the time a tiger team forms, several people may have an explanation for what went wrong. Start by sorting what the team knows from what it suspects.
| Bucket | What goes here | Example |
|---|---|---|
| Confirmed | Findings supported by logs, data, documents, or reproducible tests | Failures began after version 4.2 shipped |
| Suspected | Plausible explanations that still need testing | A new API dependency may be increasing timeouts |
| Unknown | Questions the team still needs to answer | Whether failures affect every region equally |
| Ruled out | Explanations the evidence no longer supports | Database capacity isn’t reaching its limit |
Review previous fixes, experiments, incident notes, and decisions as part of that exercise. A route that looks promising today may already have been tested six months ago. From there, turn the strongest explanations into a short hypothesis queue. For each one, capture what you think is happening, what evidence supports it, how you’ll test it, and what the result tells you.
Order the queue by what you stand to learn. A theory that could explain most of the problem and takes an hour to test deserves attention before one that needs a week of engineering work.
Save the calls that could affect what the team does next or that someone may reasonably need to understand later. That might include an accepted risk, a rejected technical path, a scope change, or a decision to stop pursuing a hypothesis.
| Decision | Evidence used | What it changes | Revisit if |
|---|---|---|---|
| Disable feature X for affected accounts | Error logs isolate failures to feature X | Removes one failure path while testing continues | Error rate stays unchanged |
| Test dependency Y next | Failures correlate with calls to Y | Moves Y up the hypothesis queue | Regional data breaks that pattern |
Review the log whenever new evidence challenges an earlier assumption, and keep the current decision visible alongside the evidence behind it.
How often a tiger team meets depends on how quickly the problem is changing. During a live outage, the team can regroup every few hours. A two-week investigation into a slow-moving data issue can usually be managed with a couple of check-ins a week.
Whatever the pace, each meeting should have a clear purpose. Fresh evidence that changes the picture, a blocker only the sponsor can remove, or a decision the team has to make together all qualify. Day-to-day progress is better documented in the written record, where people can review it whenever they have a spare moment.
If the work stretches past a couple of weeks, schedule a midpoint review. It gives the team a chance to step back from the daily investigation and ask:
Honest answers at this stage can keep the team from spending its second half on the wrong problem.
Stakeholders usually don’t need a seat in any of this. A short written note every few days, covering what the team has learned, what it has decided, and where it’s stuck, keeps them close enough to step in when they’re needed.
A fix can look convincing the day it ships and still fall apart once normal traffic, volume, or edge cases return. That’s why the team shouldn’t declare the problem solved the moment the numbers improve.
How long to monitor the fix depends on how often the problem has a chance to resurface. For example, a high-volume service might give you a reliable signal within hours. A monthly financial close may need another full cycle before anyone can say the fix has held.
While you wait, keep two numbers in view:
If the numbers start drifting back, treat that as new evidence. Bring it into the investigation and see what it changes. It might move a different hypothesis to the top of the queue, or reveal that the original diagnosis only explained part of what was going wrong.
By this point, the team has already built most of what a handoff needs. The working brief, evidence, tests, decision log, and validation data are all sitting in the record. Rewriting them into a polished closing report adds work and little else.
Instead, pull those records together and make the remaining ownership impossible to miss. The permanent owner should walk away knowing:
Before anyone steps away, answer: Who gets the call if the problem comes back?
Once the result is reached and the answer is settled, the tiger team can disband. Members return to their regular work, the ongoing responsibilities move back into the normal structure, and the investigation stays on record for whoever needs it next.
Tiger teams tend to enter at one of two points. Some are assembled once a problem is already affecting the business. Others are brought in earlier, while there’s still time to expose weak points and change the plan.
The difference comes down to what the team is trying to learn.
This is the version most people associate with tiger teams. It could be a launch slipping, an outage recurring, a critical process breaking down, or several teams trying fixes without reaching the source.
At that point, the tiger team has evidence to work from. The job is to connect those signals, narrow down the root cause, test the strongest explanations, and get the system back to a stable state.
Reaching this stage can be costly. In Uptime Institute’s Global Data Center Survey 2025, 87% of respondents who had experienced an impactful outage in the past three years said it could have been avoided with better management, processes, or configuration.
Their Annual Outage Analysis 2026 also found that 57% of respondents said their most recent major outage cost more than $100,000, while one in five put the cost above $1 million. These figures are specific to data centers, so they shouldn’t be treated as a universal benchmark for every tiger team.
But they do show why the work after a reactive intervention shouldn’t stop with the immediate fix. Once things are stable, look at the conditions that let the problem get that far.
A preventive tiger team starts while there’s still room to alter the plan.
NASA has used this approach directly. When its Engineering and Safety Center assembled an assessment team to review the CALIPSO spacecraft’s propulsion bus, the group built a fault tree to examine possible failure paths before launch. In NASA’s retrospective on 15 years of the Engineering and Safety Center, NESC Director Tim Wilson described the approach as:
Our approach was to lay out a fault tree that showed everything that could possibly go wrong and determine if the appropriate controls were in place during the build process to ensure those fittings wouldn’t leak
That’s close to the spirit of the early aerospace tiger team. The team is given something consequential and asked to challenge it before the consequences arrive.
The output should leave the wider project with something concrete to act on, such as:
Tiger teams show up in construction, software, and government. Graham, Grafana Labs, and the UK Public Sector Fraud Authority each formed one around a bounded problem with a clear finish line. The expertise changed from case to case, while the structure stayed the same.
Civil engineering contractor Graham formed a tiger team around a repetitive but expensive part of its South Bank Quay project. Crews had 166 tie rods to install, each stretching more than 38 meters and anchoring the quay wall to an anchor wall.
The team brought together Graham’s project staff, the installation subcontractor, the tie rod manufacturer, and other supply-chain partners. They first mapped the installation process, then measured the work on site using time-lapse footage and a time-and-motion study. Once they had a baseline, they changed the process and measured it again.
According to the Get It Right Initiative’s case study, installation time fell from 185 minutes to 91 minutes per tie rod, a reduction of about 51%, while the number of tasks dropped by 37%. Graham also reported saving 14 days on the program and an estimated £230,000.
The team found smaller changes across the process, tested them against the same work, and could show exactly what improved.
Grafana Labs’ open-source releases had become increasingly manual, while responsibility for improving them was scattered across several engineering teams. Three senior engineers who had already been working on parts of the problem were brought together for one quarter to simplify the workflow, automate builds, and support direct patching for Grafana Cloud channels.
The Release Tiger Team drastically cut manual steps and made security releases easier to handle. By the end of the quarter, the work had also made a longer-term gap clear enough for Grafana to create a dedicated release group.
That progression helps address recurring software release management problems. A short intervention can solve the immediate friction while also showing where ongoing responsibility belongs. Grafana has applied the same model elsewhere, including a tiger team that helped land a major partner.
In 2022, the UK’s Public Sector Fraud Authority used the tiger team model while new energy-support schemes were still being designed.
The team brought together fraud specialists from government departments, Ofgem, energy settlement bodies, and outside energy-sector experts. According to the Public Sector Fraud Authority’s 2022–23 annual report, it completed fraud impact and risk assessments across six new energy schemes in the Department for Business, Energy & Industrial Strategy and one in HM Treasury.
The work started early enough for program teams to act on what the specialists found. BEIS said the range of expertise helped build fraud considerations into the schemes and gave ministers visibility into key risks while the programs were still taking shape.
These five mistakes can undermine a tiger team even when the problem and team structure are clear.
When the pressure is high, it’s tempting to push three or four promising fixes together and see whether the problem disappears.
That can get you to a better result quickly, but it leaves an awkward question behind: Which fix worked? If an engineering tiger team updates a dependency, changes a timeout, and increases capacity in the same release, a drop in failures tells you very little about the cause. It also makes rolling back harder if another problem arises later.
The fix: When you can, make changes in a sequence you can observe. Record what changed and what happened before adding the next intervention. For urgent cases where changes have to ship together, document the bundle so you can separate and test its parts once the immediate pressure has passed.
A fresh perspective can help, but the people who work with the affected system every day often know about exceptions, workarounds, and dependencies that never made it into the documentation. Leaving them out can produce solutions that look clean from the outside and fail as soon as they meet the real workflow.
This applies beyond engineering. A tiger team redesigning an approval process, for example, should hear from the people who process those approvals every day, not only the leaders who oversee them.
The fix: Include at least one person involved in the day-to-day work, or bring them into the investigation early. Ask where the documented process differs from what people do in practice.
Once people feel that the tiger team is trying to identify who caused the problem, they may become more cautious about what they share. Someone may leave out a bad call they made earlier, avoid mentioning a failed workaround, or defend an old decision because they feel personally responsible for it. That leaves the team with less evidence and makes the real cause harder to find.
The fix: Keep the review centered on decisions, systems, and conditions. If there’s a separate performance or conduct issue, handle it through the appropriate process rather than folding it into the tiger team’s investigation.
A promising fix can introduce a new failure of its own. Teams get into trouble when they plan how to deploy a change but not how to reverse it. A rollback also becomes harder once customers, data, or downstream systems have started interacting with the change.
The fix: Before a high-risk intervention, decide how you’ll reverse it, what evidence will trigger that reversal, and who can make the call. Test the rollback path when the cost of getting it wrong is high.
Urgent work often starts wherever people can move fastest: a private chat, an ad hoc spreadsheet, a temporary document, or a separate project board. The trouble starts when decisions, evidence, and tasks spread across all of them.
Someone sees the latest decision in the chat while another person acts on the old one in a spreadsheet. After the team closes, reconstructing what happened becomes even harder.
The fix: Pick one place for the current decision, owner, and status of the work. Other tools can still hold logs, analysis, or conversations, but they should point back to the same working record when something changes.
A tiger team can have the right people and a sharp brief, then lose time because the evidence sits in one tool, decisions are made in another, and follow-up work lives somewhere else. Here’s how one team might run the whole effort in ClickUp, using the checkout-failure example from earlier.
Say checkout failures have climbed to 4% after a recent release, and the sponsor has asked a tiger team to get them back below 1%. The lead starts by creating a Folder called “Checkout failures tiger team” inside the engineering Space. The work stays close to the team that will own it once the tiger team disbands.
Inside the Folder, the lead creates a ClickUp Doc for the working brief. It holds the exit condition (failures below 1% for 2 full weeks), the baseline, the success and guardrail metrics, what’s in and out of scope, who can make which calls, and a decision log table. During the first working session, the team agrees to test the new payment API dependency first. The lead highlights that line in the Doc and turns it into a Task without leaving the brief.
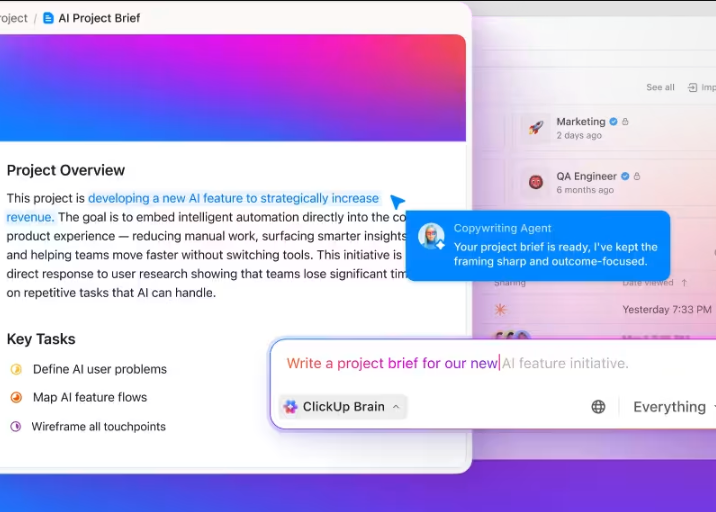
That first Task goes into a List called Hypothesis queue, along with every other theory the team wants to test. The List’s statuses follow the evidence buckets from step 3, with one added for work in progress: Suspected, Testing, Confirmed, and Ruled out. Unknowns can live in the brief as open questions.
As tests finish, Tasks move across, and the whole team can see what’s known and what’s still a guess. The lead adds 3 Custom Fields to every hypothesis: Impact, Test cost, and Result. Sorting by Impact and then Test cost puts the theories that could explain the most, and take the least time to check, at the top.
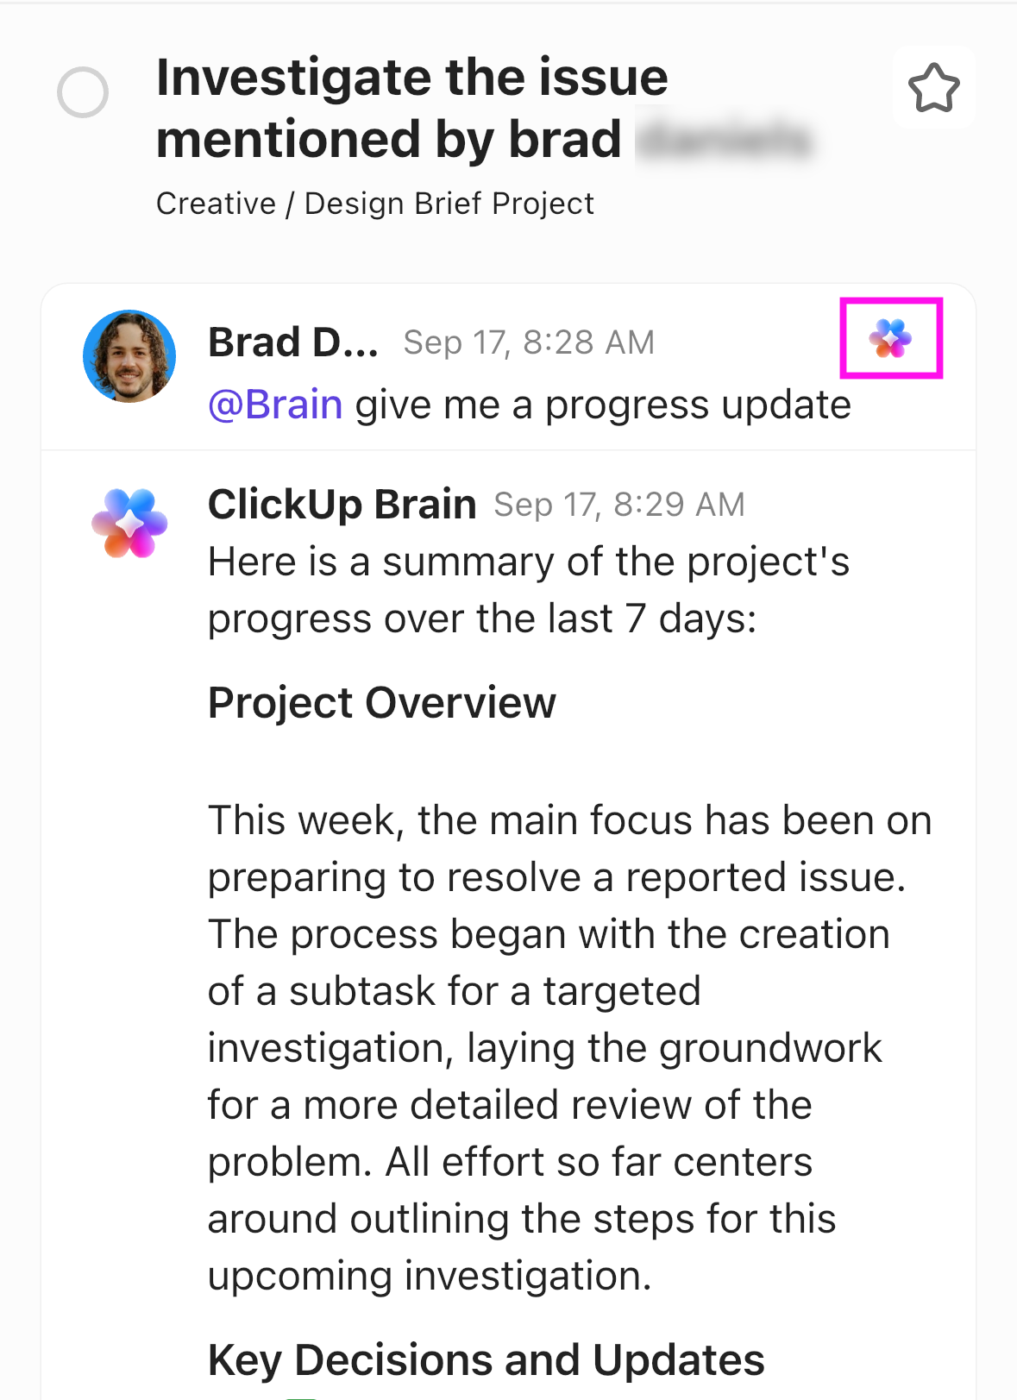
Before the engineers run the API test, one of them asks Brain²: “Have we tested payment provider timeouts before?”
Brain² searches Tasks, Docs, Chat, and connected apps through Enterprise Search, and it turns up a similar investigation from 6 months ago, with sources linked. The team reads what was ruled out last time, adjusts the test, and pastes the links into the hypothesis Task so the history stays attached to it.
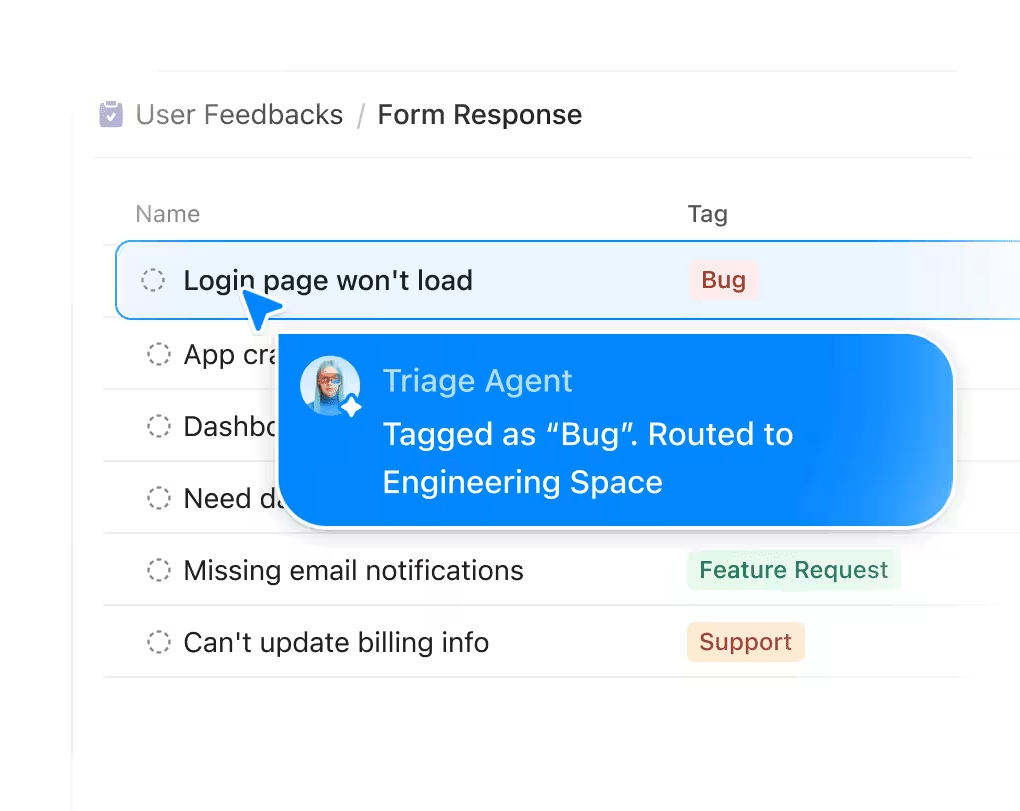
By the end of week 1, people outside the team have started raising related issues: a pricing display bug, a slow account setup flow. Each one could easily turn into new work.
The lead sets up a ClickUp Form that sends these into a separate List called Parking lot. Each submission becomes its own Task there, and the sponsor reviews the List at each check-in to decide whether anything belongs in scope.
The sponsor needs to step in when a decision is waiting on them, but they don’t need to follow the rest of the investigation day to day.
The lead adds a checkbox field called “Needs sponsor decision” and builds a Dashboard with 3 cards: one for Tasks waiting on the sponsor, one for blocked or overdue work, and one tracking the failure rate as a number field. The sponsor opens that one page before each check-in.
This walkthrough shows how to build a project dashboard around the signals that need attention:
In week 2, the team disables a feature for affected accounts as a temporary workaround, and that decision needs another look in 7 days. The lead sets the Task’s due date to that day and adds an Automation that notifies the owner when the date arrives.
Stakeholder updates are also starting to take up the lead’s time. A Super Agent now posts a short summary every Monday and Thursday, covering new decisions, blockers, and anything waiting on the sponsor.
Failures stay below 1% for 2 full weeks, so the team has met its exit condition. The lead moves the remaining open Tasks into the payments team’s List and reassigns them. The last entry in the decision log names the new owner and the conditions that should start a new investigation. Then the lead archives the Folder.
Where it taps out: ClickUp won’t replace the systems producing the evidence. If your tiger team is responding to a production outage, keep your logs, alerts, and live telemetry in the monitoring or incident tool built for them. Bring the decisions, follow-up work, and context into ClickUp where the wider team can act on them.
Best for: Tiger teams running for days or weeks, especially when several people test ideas, make decisions, pull context from past work, and hand the result back to a permanent owner.
A tiger team is a controlled exception. You’re temporarily concentrating expertise, authority, and attention around a problem that the usual structure can’t handle at its normal pace.
That makes the ending just as important as the intervention. Once the problem is under control, the team should be able to step away without taking its decisions, evidence, or unfinished work with it. If the organization still depends on the same temporary group to keep things running, the problem has changed.
What remains after the handoff is the record of how the problem was understood and solved. In ClickUp, that record remains searchable after the tiger team’s Folder is archived, so the next owner can find the brief, hypotheses, and decision log without having to reconstruct them.
There’s no universal headcount. Keep the core group as small as the problem allows, then bring in other specialists when you need their knowledge. A larger roster adds more communication and scheduling overhead. If someone only needs to provide evidence or answer a specific question, they don’t necessarily need to become a permanent member of the tiger team.
Yes. A tiger team doesn’t need to share a physical room. What it does need is fast access to the same evidence, clear ownership, and a reliable place for decisions. For a distributed team, keep the working record current and reserve synchronous calls for decisions, blockers, or evidence that changes the investigation. That prevents time-zone differences from turning every update into another meeting.
No. A tiger team isn’t a formal Scrum role, event, or accountability. The official Scrum Guide defines a Scrum Team around the Product Owner, Scrum Master, and Developers. A company using Scrum can still form a tiger team around a problem that crosses existing team boundaries. You just need to decide how that temporary work interacts with current Sprint commitments and Product Goals.
No. The model started in aerospace and remains common in engineering and security, but the structure can work anywhere a difficult problem needs concentrated expertise. A tiger team could investigate fraud, redesign an operational process, resolve a regulatory issue, or work through a commercial problem. The expertise changes with the problem.
Yes. External specialists, vendors, consultants, or supply chain partners can join when they have knowledge the internal team doesn’t. Give them the same clarity around scope, access, confidentiality, and decision rights as internal members. They should be there because the investigation needs their expertise, not simply because their organization is affected by the outcome.
The team should still leave the organization with a narrower problem than it started with. That may mean identifying what has been ruled out, isolating the remaining unknowns, documenting which interventions failed, and showing where the current team has reached the limits of its expertise or authority. From there, leadership can decide whether the work needs a different specialist, more time, a permanent owner, or a larger structural change. Failing to reach the original exit condition doesn’t erase what the investigation learned.
“Cross-functional” describes who is on the team. “Tiger team” describes why the group has been assembled and how long it is expected to exist. A cross-functional team can be permanent and own an ongoing product, process, or business area. A tiger team is formed around a specific problem and disbands once that assignment is finished. A tiger team is often cross-functional, but the two terms aren’t interchangeable.
Manasi Nair
Max 24min read
Manasi Nair
Max 20min read
Sudarshan Somanathan
Max 22min read
© 2026 ClickUp